

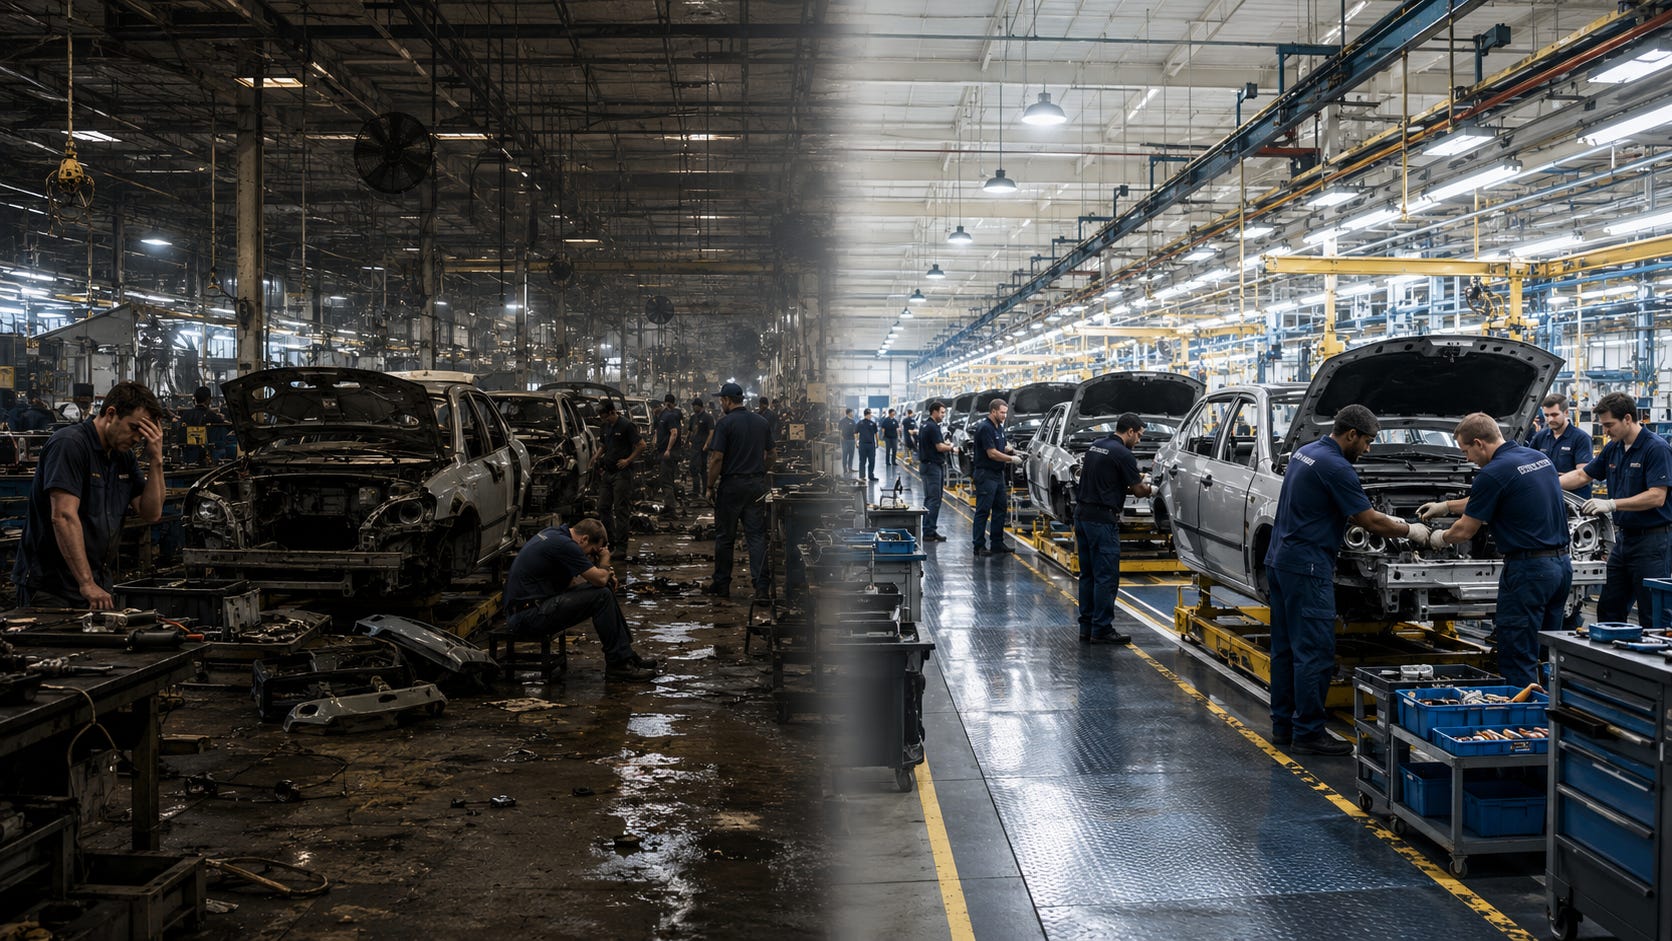
In 1982, General Motors closed its assembly plant in Fremont, California and laid off thousands of workers. By almost every measure it was the worst plant in the GM system. Absenteeism ran above 20%, high enough that on some mornings the line could not start. Workers drank on the job. A few of them slipped Coke bottles inside the door panels so the finished cars would rattle all the way home and annoy the customer. When GM management talked about Fremont, they did not talk about training or tooling or design. They talked about character. Those people, was the phrase.
Two years later the plant reopened as NUMMI, a joint venture between GM and Toyota. Toyota rehired the same workers. More than 85% of the starting workforce came from the group GM had laid off, including many of the people with the worst records, and the union leadership came back with them. GM thought it was madness. Toyota bet that its production system was strong enough to make the question moot. This American Life told the whole story years ago, and it has stayed with me.
Within roughly a year, Fremont was building cars at quality levels near the top of the GM system. Absenteeism fell into the low single digits. Same people, same building, a different operating system.
The Question a Reader Asked
A couple of weeks ago I wrote The Vital Few, about Price’s Law and the way leaders misuse it. That piece ended on a claim: the concentration of output you see in your organization is partly a property of the organization, not only of the people in it. You built some of it and therefore, if you built it, you can build more of it.
Several readers asked the obvious follow-up. How would you operationalize that? What changes should I make on Monday?
Almost every instrument we use to manage performance assumes the opposite of what happened at Fremont. We rate individuals. We compare individuals in calibration. Our promotion rubric counts individual output. Our improvement plans correct individuals. We pay a premium to hire individuals, on the theory that whatever made them good travels with them in a backpack. We produce performance as an organization and then account for it one person at a time.
An Old Bias With a Budget
In 1977 the Stanford psychologist Lee Ross named the reflex behind this. He called it the fundamental attribution error, our tendency to explain other people’s behavior by their character while discounting the situation they were standing in. The driver who cuts you off is reckless. You probably don’t stop to wonder whether he is racing someone to the hospital. It became one of the best-known findings in social psychology, and it describes most of what happens in a calibration room.
In 2000, Steven Scullen, Michael Mount, and Maynard Goff published a study in the Journal of Applied Psychology covering two datasets of managers, about 2,350 in one and 2,140 in the other, each rated on three dimensions by seven raters drawn from their bosses, peers, and subordinates. Idiosyncratic rater effects, the quirks and tendencies of whoever holds the pen, accounted for 62% and 53% of the variance in the ratings. The performance of the person being rated accounted for 21% and 25%. The rater explained more of the score than the ratee did. That does not mean 62% of your annual review is rater bias; these were developmental ratings, not compensation decisions. It does mean who does the evaluating shapes the result more than most performance systems admit.
The damage does not stop when you submit the form. Once you assign a label, you start building the conditions that produce the next one. The person you marked strong gets the visible project, the senior mentor, and the benefit of the doubt in a bad quarter. The person you marked weak gets the maintenance work, the ambiguous assignment nobody wants to own, and a manager who has already decided how the story ends. With each cycle the evidence looks more convincing, because we manufactured it. Fatalism about talent is a decision you made three cycles ago.
I wrote in The Measurement Trap about how we adopt measures whose value we never checked. Performance ratings belong on that shelf. In Perfectly Designed for These Results I made the broader argument that organizations produce the outcomes they are built to produce. The narrower question is what to change in the machinery once you accept that.
Two Other Rooms
NUMMI is a factory, which makes it easy to file the lesson under manufacturing and move on. The same thing happened in a hospital system and at a software company.
Beginning in 2003, Peter Pronovost of Johns Hopkins ran a project through the Michigan hospital association across intensive care units around the state. Central line infections were common and expensive, and they killed people. The intervention did not depend on finding better doctors. It was five evidence-based steps, a checklist, a cart that put the supplies in one place, and a culture where a nurse could stop a physician who skipped a step. Across 103 participating ICUs, most units nearly eliminated the infections, and the improvement held through 18 months of follow-up. Same clinicians, different system.
Google spent years on Project Aristotle trying to identify what made some of its teams excellent, expecting to find the right mixture of talent. The researchers concluded that who was on the team mattered less than how the team worked together, with psychological safety at the top of the list. Google, of all companies, went hunting for the star ingredient and came back with the recipe for the entire meal.
Three settings across three decades gave the same answer. People produce output together, and the share of it that comes from the system around them is larger than our performance machinery is built to admit.
None of this makes people interchangeable. They are not, and the concentration of output is real. The question worth asking is how much of the difference between two people travels with them when they walk out the door. Boris Groysberg spent a decade tracking Wall Street analysts and found that stars who moved to a new firm usually got worse. The ones who held their performance had brought their teams with them, or landed somewhere with stronger capabilities. Part of what you call a star is a description of the scaffolding around them.
If the scaffolding does this much of the work in a car plant, an ICU, a software team, and a trading floor where talent is supposed to be the most portable thing there is, it deserves the same attention you give the hiring plan.
Building the Scaffolding
Five places to start.
Make concentration visible. You can report attrition to two decimal places and you cannot say how many people could carry each critical system, process, or customer relationship. Count it. Put the number next to the metrics your leadership team already reviews every month. It will be worse than you expect. Publish it and someone has to own it, which is when staffing arguments get concrete.
Treat a slow ramp as a system event. When someone capable underperforms, you reach for the hiring miss, which puts the fault outside your control. Ask the other question first. What in your onboarding, your documentation, or your choice of manager made this predictable? If your strong hires take nine months to become useful, that is a fact about you.
Credit the capability people build in others. If personal output is the only thing that moves someone to the next level, you have told your strongest people that developing the bench is a hobby they pursue at their own expense. Put it in the rubric. Did the systems this person owned become runnable by more people than before? Did anyone get better because this person was here? This is the highest-leverage change on the list, because it turns your vital few into multipliers rather than bottlenecks without asking them to be more generous than their incentives allow.
Review the role, not the person. You already run post-incident reviews when a system fails. A resignation from someone load-bearing is an outage with a longer fuse. The exit interview asks why the person left, which is useful and insufficient. Ask what the role was doing to whoever held it. Count the escalations that landed there, and the years since anyone else touched that code, that account, that relationship.
Close the seam. Do not swap individual-focused HR for team-focused management but do stop treating them as separate problems. The unit of performance is a person in a context. HR measures the person and ignores the context. Cross-functional management measures throughput and ignores the person. Nobody owns the seam between them, and the seam is where your people either do their best work or stop trying.
The Excuse This Is Not
You can hide inside systems thinking. If every shortfall belongs to the conditions, nobody is accountable for anything, and you have traded one bad model for a worse one.
The individual is accountable for effort, behavior, and judgment. The leader is accountable for the conditions. Someone who is cruel to colleagues does not get a system’s defense, and I have argued before that the brilliant jerk is a losing trade no matter what they produce. A leader who blames the system for conditions they control is running the same dodge in the other direction. That is its own version of being too nice, the version where you do not solve the problem. You hand it to everyone else as a tax.
Both halves have to hold at once. Toyota did not lower the standard at Fremont. Any worker who saw a defect had to stop the entire line, a higher bar than GM ever set. The company built a system that made meeting that bar possible, and then held people to it.
The Exercise
Pull up your last review or calibration cycle and find the person you rated lowest.
Now write one honest sentence describing the conditions that person worked in. Who managed them, and what did their onboarding look like? How clear were the problems that landed on their desk?
If you cannot write that sentence, you did not rate a person. You rated a shadow, and then you filed it, and next quarter you will file another one just like it.
If you can write it, ask the harder question. How many of the things in that sentence were inside your control, and what did you do about any of them before the rating was due?
Somewhere in your organization there is a Fremont. The same people, waiting on the rest of it.
Such a thoughtful and well written article. I am curious what you think the alternative to current performance reviews is given the flaws you pointed out. Or is your point that performance reviews could still be there but need to be coupled with role reviews/ systems reviews?
Superb article. I hadn't listened to the recording from This American Life before. It was fascinating how non-obvious it was for GM to choose to do things differently to replicate Nummi's success elsewhere, and how the success factors had much to do with the organisational conditions and the system behind what was visible, including relationships with suppliers. And as you say, it's applicable in many other industries and still the case today. I work entirely with large, bureaucratic institutions and companies, and while you have to start small and do things differently *somewhere* - to show it's possible and for people to experience it for themselves - it's so true that you gotta simultaneously raise awareness of the need to change the organisational practices and situation responsible for the status quo, or there will be an organ-rejection of the new. And so much depends on support and air cover from the top.